Blog
Test Data Management: Strategies and Best Practices
Adwitiya Pandey
Published on

Table of contents
Lorem ipsum
Lorem ipsum
Lorem ipsum
Lorem ipsum
Lorem ipsum
The Test Data Problem Nobody Talks About
Most automation programmes fail quietly. The tests run, results come back, and engineers spend hours investigating failures that turn out to have nothing to do with the application. The culprit is almost always the same: the data underneath the tests was wrong, stale, incomplete, or missing entirely.
The scale of this problem is larger than most teams acknowledge. A meaningful portion of every QA team's working week disappears into data preparation, data debugging, and data-related false failures. The tests themselves are fine. The application is fine. The data is the problem.
Test data management is the discipline that addresses this systematically. Without it, automation programmes accumulate a hidden tax that grows with every new feature, every new environment, and every new compliance requirement added to the stack.
What Is Test Data?
Test data is the collection of input values that an automated or manual test uses when interacting with an application. These values represent the inputs a real user might provide under actual usage conditions. A test script opens the application, identifies the relevant fields, inserts the test data, and evaluates the outcome.
Consider a login page. Testing it properly requires more than one valid username and password combination. It requires data that covers every scenario the application needs to handle correctly.
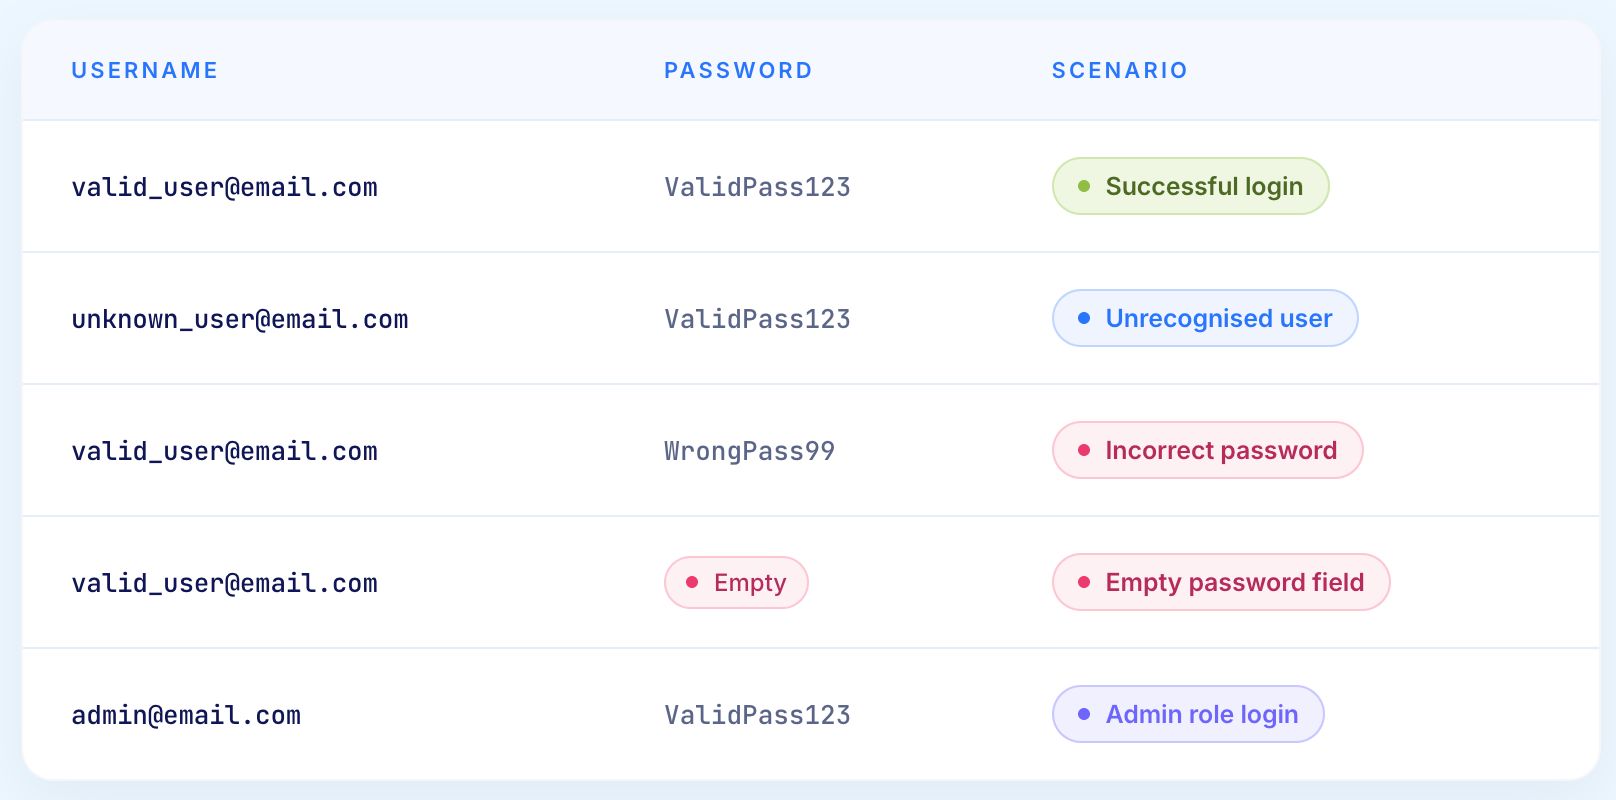
A single login page requires at minimum five to ten data combinations for adequate coverage. A checkout flow requires significantly more. An enterprise application with hundreds of features requires thousands of data combinations across dozens of environments.
What Makes Test Data High Quality?
Not all test data is equal. Four characteristics determine whether test data is fit for purpose.
Relevance: Data should match the scenario it is meant to test. Using a valid credential pair to test an invalid login flow produces a result that means nothing.
Availability: Data that exists but cannot be accessed by the right person at the right time provides no value. Access controls and provisioning processes are part of the TDM problem.
Currency: Applications change continuously. Test data that accurately reflected the application six months ago may be structurally incompatible with it today. Stale data produces failures that waste investigation time on non-existent defects.
Compliance: Production data frequently contains personally identifiable information, financial records, and health data protected by regulations including GDPR, HIPAA, and PCI DSS. Using it untreated in test environments creates regulatory exposure that TDM is specifically designed to prevent.
What is Test Data Management?
Test data management (TDM) encompasses the processes, tools, and practices for creating, maintaining, provisioning, and governing data used in software testing. Effective TDM ensures tests have access to appropriate data when needed while protecting sensitive information and maintaining data quality.
The Scope of Test Data Management
TDM addresses multiple concerns:
Data Creation: Generating or acquiring data that supports test scenarios
Data Provisioning: Delivering appropriate data to test environments when needed
Data Maintenance: Keeping data current, valid, and aligned with application requirements
Data Protection: Securing sensitive information while enabling realistic testing
Data Governance: Establishing policies, ownership, and compliance for test data
Each concern requires attention. Neglecting any area creates gaps that undermine testing effectiveness.
Why Test Data Management Matters
Poor test data management creates cascading problems:
False Failures: Tests fail due to data issues rather than application defects. Teams waste investigation time on phantom problems.
False Passes: Inadequate data fails to exercise edge cases. Tests pass while real defects hide in untested scenarios.
Flaky Tests: Data dependencies cause inconsistent results. The same test passes and fails unpredictably.
Compliance Risk: Sensitive production data exposed in test environments creates regulatory and security vulnerabilities.
Maintenance Burden: Manually managed data becomes stale, requiring constant refreshes and repairs.
Organizations report that data issues cause 30% to 50% of test failures. Addressing test data management eliminates this waste.
Types of Test Data
Understanding different test data types enables targeted test coverage and appropriate data strategy selection.
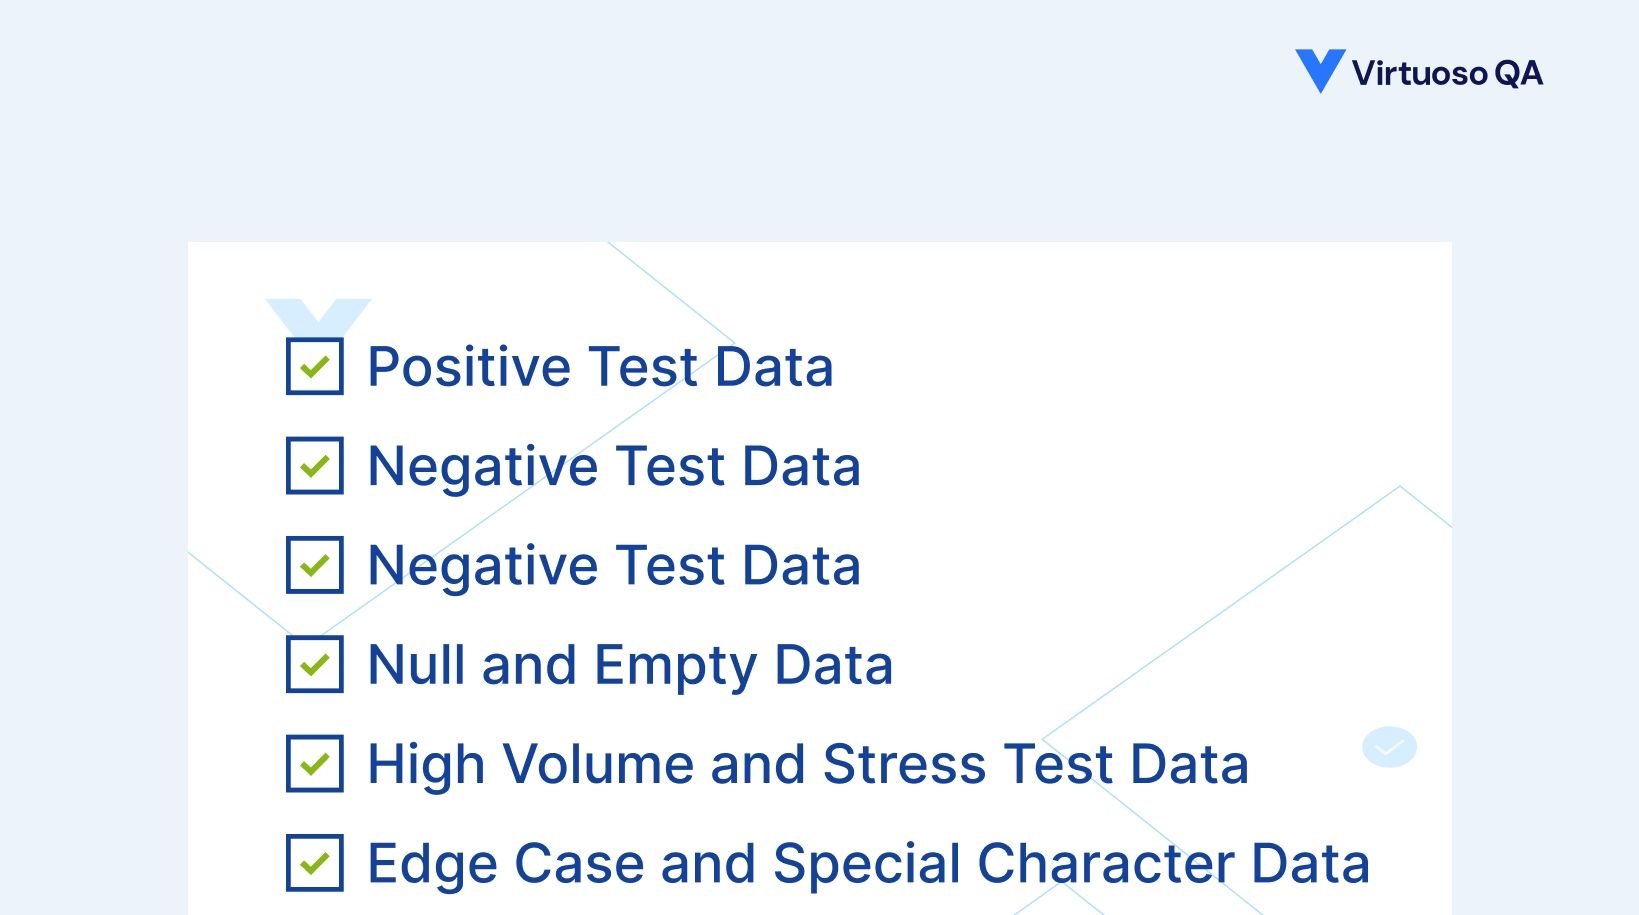
1. Positive Test Data
Valid input values within expected parameters that verify correct system behaviour under normal conditions.
Example: Properly formatted email addresses, valid credit card numbers, or correctly structured customer records.
2. Negative Test Data
Invalid or unexpected inputs designed to test error handling and validation logic. Examples include malformed data, out-of-range values, and inputs violating business rules. Negative testing reveals how applications respond to user mistakes or malicious input.
3. Boundary Test Data
Values at the edges of acceptable input ranges. Boundary testing targets:
Minimum and maximum permitted values
First and last valid entries
Values immediately inside and outside boundaries
Systems frequently fail at boundaries. Testing these edges catches defects that mid-range values miss.
4. Null and Empty Data
Tests how systems handle missing information:
Null values in required fields
Empty strings versus null distinctions
Missing optional parameters
Incomplete records
5. High Volume and Stress Test Data
Large datasets designed to evaluate system performance under load:
Volume testing with realistic data quantities
Stress testing with extreme data loads
Concurrency testing with simultaneous data operations
6. Edge Case and Special Character Data
Unusual but valid inputs that may cause unexpected behaviour:
Unicode and special characters
Extremely long strings
Scientific notation numbers
Locale-specific formats
Comprehensive test coverage requires data representing each type. AI-powered test data generation can produce variations across all categories automatically, ensuring thorough scenario coverage.
Effective Test Data Management Benefits
Effective TDM delivers measurable improvements across development velocity, quality, compliance, and cost.
1. Accelerated Release Cycles
When test data provisions in minutes rather than days, development teams maintain momentum. Virtual data copies enable parallel testing without waiting for shared resources. Organisations report release cycle acceleration of 25% to 50% with mature TDM practices.
2. Improved Software Quality
Comprehensive test data enables complete scenario coverage. Edge cases receive proper testing. Defects surface during development rather than production. Teams shift quality left, catching issues when fixes cost less.
3. Reduced Infrastructure Costs
Data virtualisation and intelligent subsetting reduce storage requirements dramatically. Instead of full production copies per environment, teams provision minimal viable datasets. Storage costs decrease by 50% to 80% in mature implementations.
4. Automated Compliance
Integrated masking and anonymisation ensure sensitive data never reaches test environments. Compliance becomes automatic rather than an afterthought. Audit trails document data handling for regulatory review.
5. Increased Tester Productivity
Self-service provisioning eliminates waiting. Testers access required data immediately without submitting tickets or writing scripts. Time previously spent on data preparation redirects to actual testing activities.
6. Elimination of False Failures
Clean, isolated test data removes data-related test flakiness. Tests pass or fail based on application behaviour, not data contamination. Investigation time decreases as false positives disappear.
Test Data Creation Methods
Different testing needs require different test data strategies. An effective Test Data Management (TDM) practice involves selecting the appropriate data creation or provisioning approach based on testing phase, data sensitivity, compliance requirements, scalability, and maintenance effort. The following methods represent the most commonly used approaches across modern testing organizations.
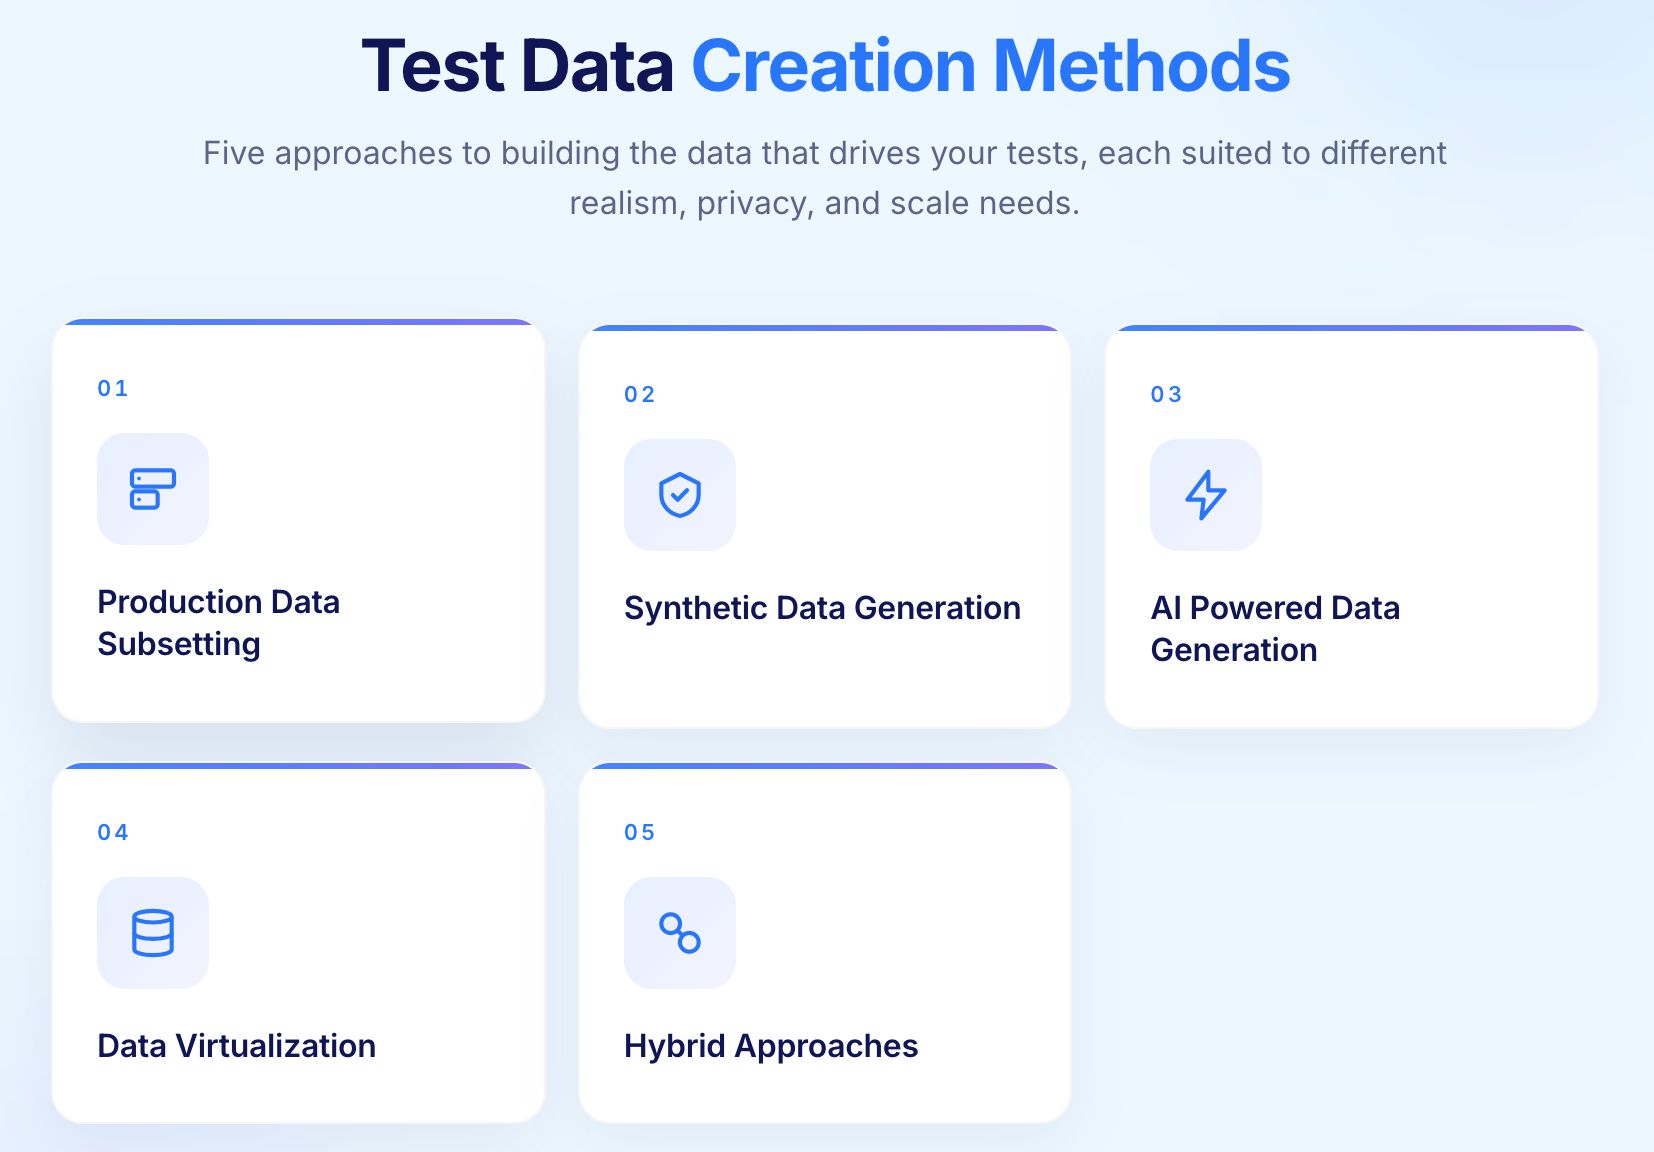
1. Production Data Subsetting
Production data subsetting involves extracting a representative portion of real production data for use in non-production test environments.
How It Works:
Identify representative production records
Extract related data maintaining referential integrity
Mask or anonymize sensitive fields
Load into test environments
Advantages:
Realistic data reflecting actual usage patterns
Complex relationships preserved naturally
Edge cases from real scenarios included
Challenges:
Privacy and compliance requirements
Data masking complexity
Refresh frequency management
Storage and transfer overhead
Best For:
Integration testing, regression testing, scenarios requiring realistic data complexity
2. Synthetic Data Generation
Create artificial test data that resembles production patterns without using real information.
How It Works:
Define data models and relationships
Specify generation rules and constraints
Generate data meeting requirements
Validate referential integrity and business rules
Advantages:
No privacy concerns with artificial data
Unlimited volume generation
Controllable edge case representation
Fresh data for each execution
Challenges:
May miss real world complexity
Requires accurate model definition
Relationship generation complexity
Validation against business rules
Best For:
Early stage testing, volume testing, scenarios with strict privacy requirements
3. AI Powered Data Generation
Leverage artificial intelligence to create contextually appropriate test data on demand.
How It Works:
AI analyzes application context and field types
Natural language prompts specify data requirements
Intelligent generation produces realistic values
Data adapts to scenario needs automatically
Advantages:
Minimal configuration required
Contextually appropriate values
Dynamic generation per execution
Eliminates static data maintenance
Challenges:
Platform dependency
Less control over specific values
May require validation for complex rules
Virtuoso QA's AI powered data generation creates realistic test data through natural language prompts. Instead of maintaining data files, testers describe what they need: "Generate a customer with international address, three open orders, and credit limit exceeded." The platform produces appropriate data instantly.
Best For:
Functional testing, rapid test creation, scenarios requiring data variety
4. Data Virtualization
Create virtual data layers that simulate data access without physical data movement.
How It Works:
Define virtual data sources
Map requests to underlying systems
Transform and filter as needed
Serve data without physical copies
Advantages:
Reduced storage requirements
Real time access to source changes
Simplified environment management
Faster provisioning
Challenges:
Performance dependencies on sources
Complexity of virtual layer management
Source system availability requirements
Best For:
Large scale enterprise testing, environments with data volume constraints
5. Hybrid Approaches
Most organizations combine strategies based on specific needs:
Production subsets for integration testing
Synthetic data for early development
AI generation for functional test creation
Virtualization for large scale scenarios
Match strategy to testing phase, data sensitivity, and practical constraints.
Test Data Management Best Practices for Automation
Reliable test automation depends on predictable, well-managed test data. Poor data practices introduce non-determinism, test flakiness, and wasted investigation effort. The following best practices help teams design scalable, compliant, and maintainable test data strategies.
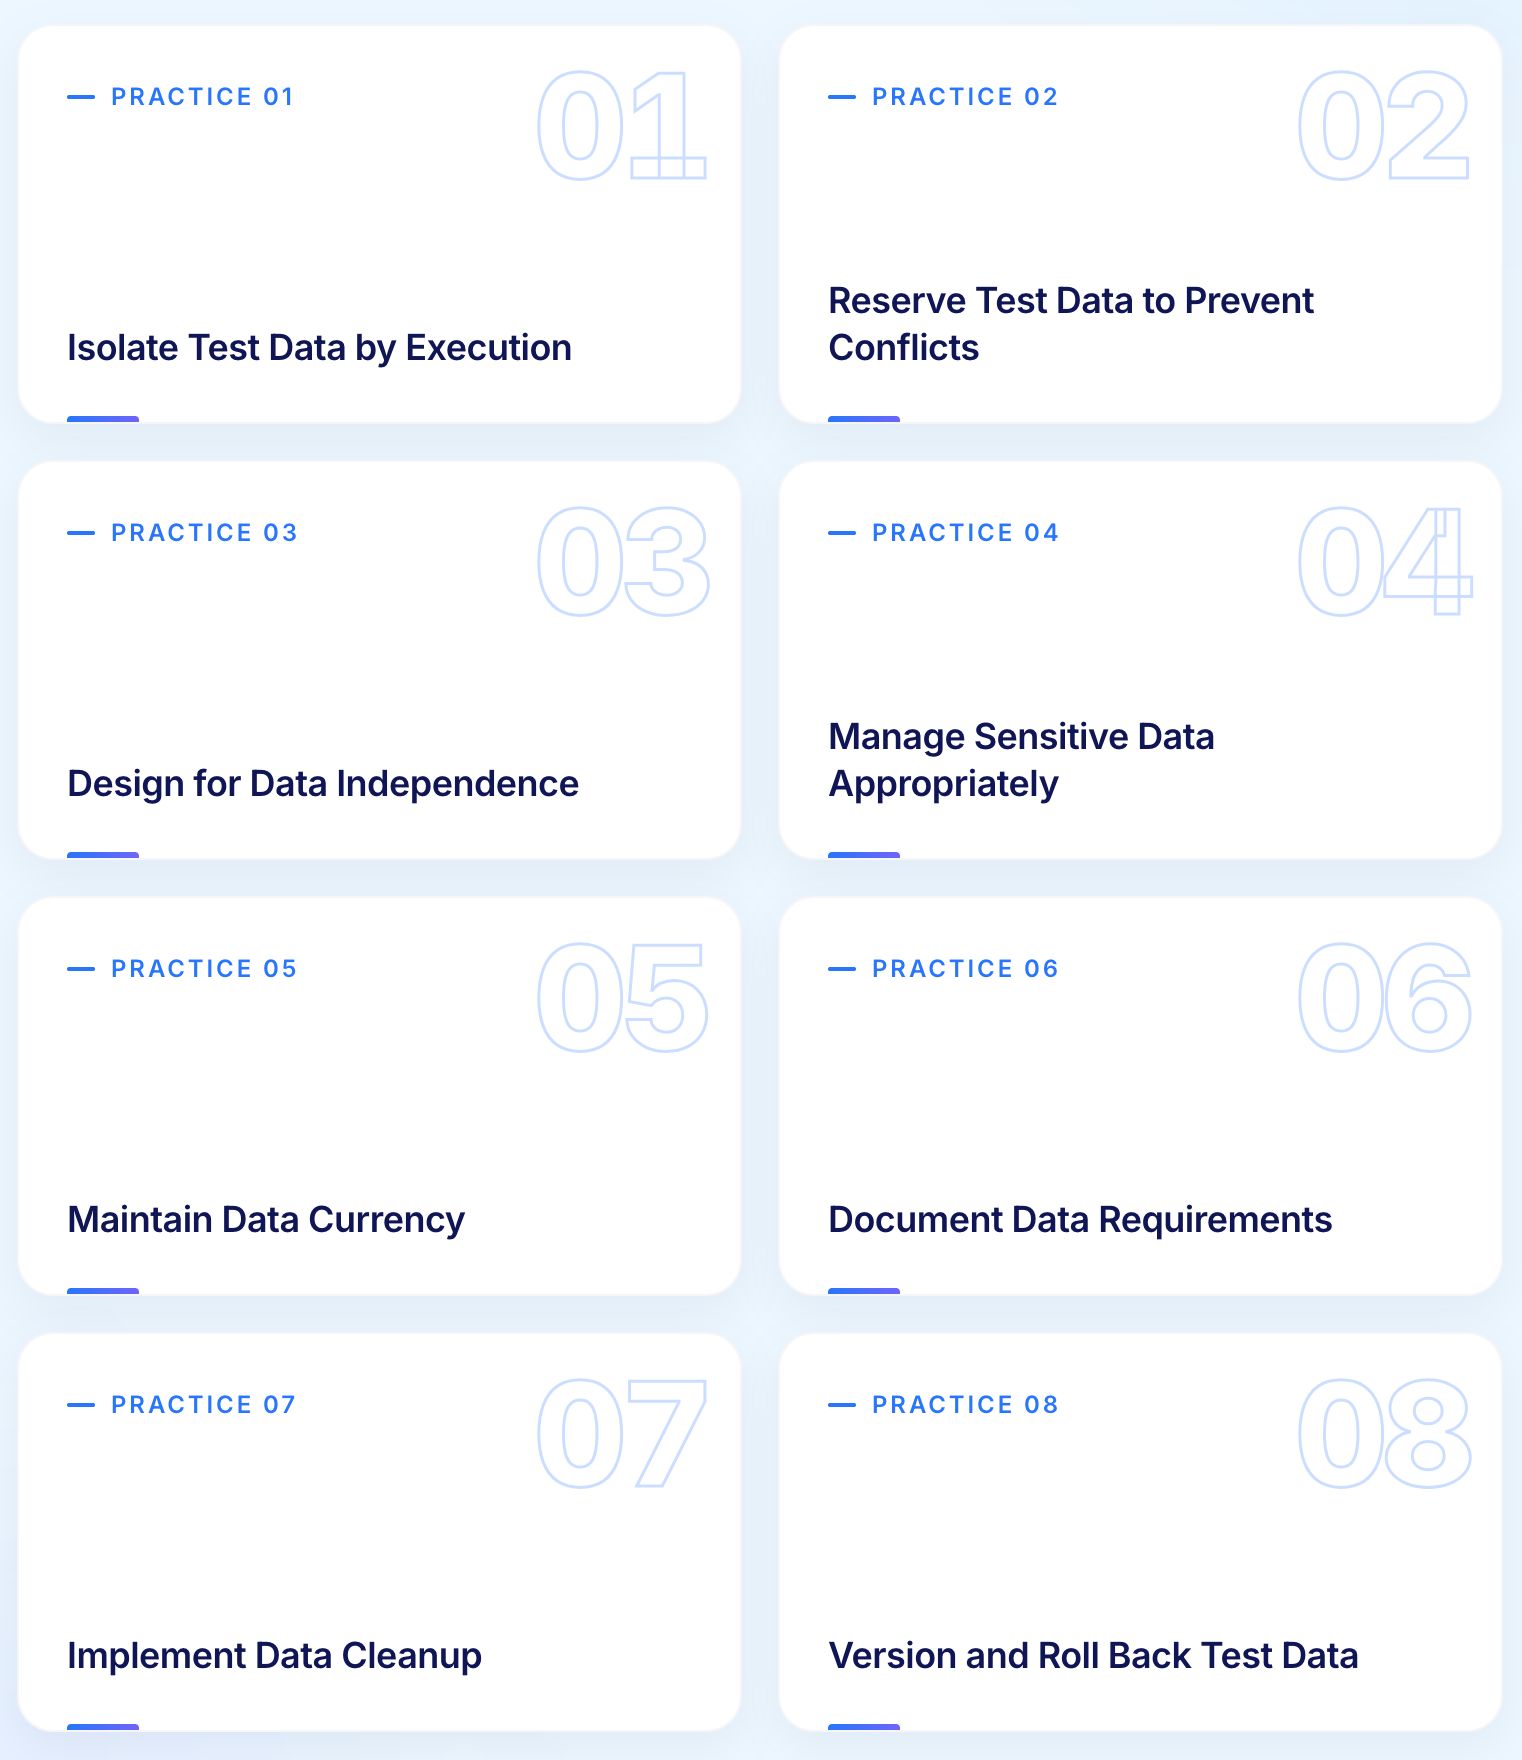
1. Isolate Test Data by Execution
Tests that share data introduce hidden dependencies and execution-order sensitivity.
Problem
Test A modifies a customer record.
Test B expects the original values.
Test outcomes depend on execution order, causing intermittent failures.
Solution
Ensure each test execution operates on isolated data. Common approaches include:
Generating unique data per test execution
Using database transactions with rollback after execution
Creating dedicated datasets per execution thread
Resetting data state before each test run
Isolation enables parallel execution, eliminates order dependencies, and improves test determinism.
2. Reserve Test Data to Prevent Conflicts
When multiple testers or automated suites run concurrently, uncoordinated data access leads to collisions.
The Collision Problem
Tester A modifies a customer account for one scenario.
Tester B simultaneously uses the same account for another scenario.
Both tests fail due to unexpected data states, resulting in time-consuming root cause analysis.
Data Reservation Solution
Implement reservation mechanisms that allocate data entities to individual testers or executions:
Exclusive locks on business entities during active tests
Time-bound reservations with automatic release
Reservation pools for commonly used test scenarios
Conflict detection and alerting on reservation violations
Reservation Best Practices
Reserve data at the business entity level (customer, order, policy) rather than table level
Set reasonable expiration times to prevent orphaned locks
Provide self-service reservation through test management interfaces
Log reservation activity for audit and troubleshooting
With reservation controls in place, parallel testing can proceed without interference while sharing the same infrastructure.
3. Design for Data Independence
Tests should not rely on data created by other tests.
Problem
Test 1 creates a customer.
Test 2 creates an order for that customer.
Test 3 validates an invoice.
Failure in Test 1 causes cascading failures across the suite.
Solution
Each test should:
Create the data it requires, or
Use stable, pre-established reference data
This enables tests to run independently, in any order, and in isolation.
Data-Driven Testing further supports independence by separating test logic from test data, enabling:
Reuse of test logic with multiple data variations
Data updates without modifying test steps
Contributions from non-technical users through data management
Platforms such as Virtuoso QA support data tables that externalize test data from test logic, allowing extensive coverage without duplicating test flows.
Watch the video below to learn how to create and manage test data inside Virtuoso QA to author data driven tests:
4. Manage Sensitive Data Appropriately
Production-derived data often contains sensitive information that has no business being in a test environment without proper handling. The categories that require protection include personally identifiable information, financial and payment details, health information, and authentication credentials. Compliance frameworks including GDPR, HIPAA, and PCI DSS impose strict requirements on how this data is handled outside production.
Recommended practices:
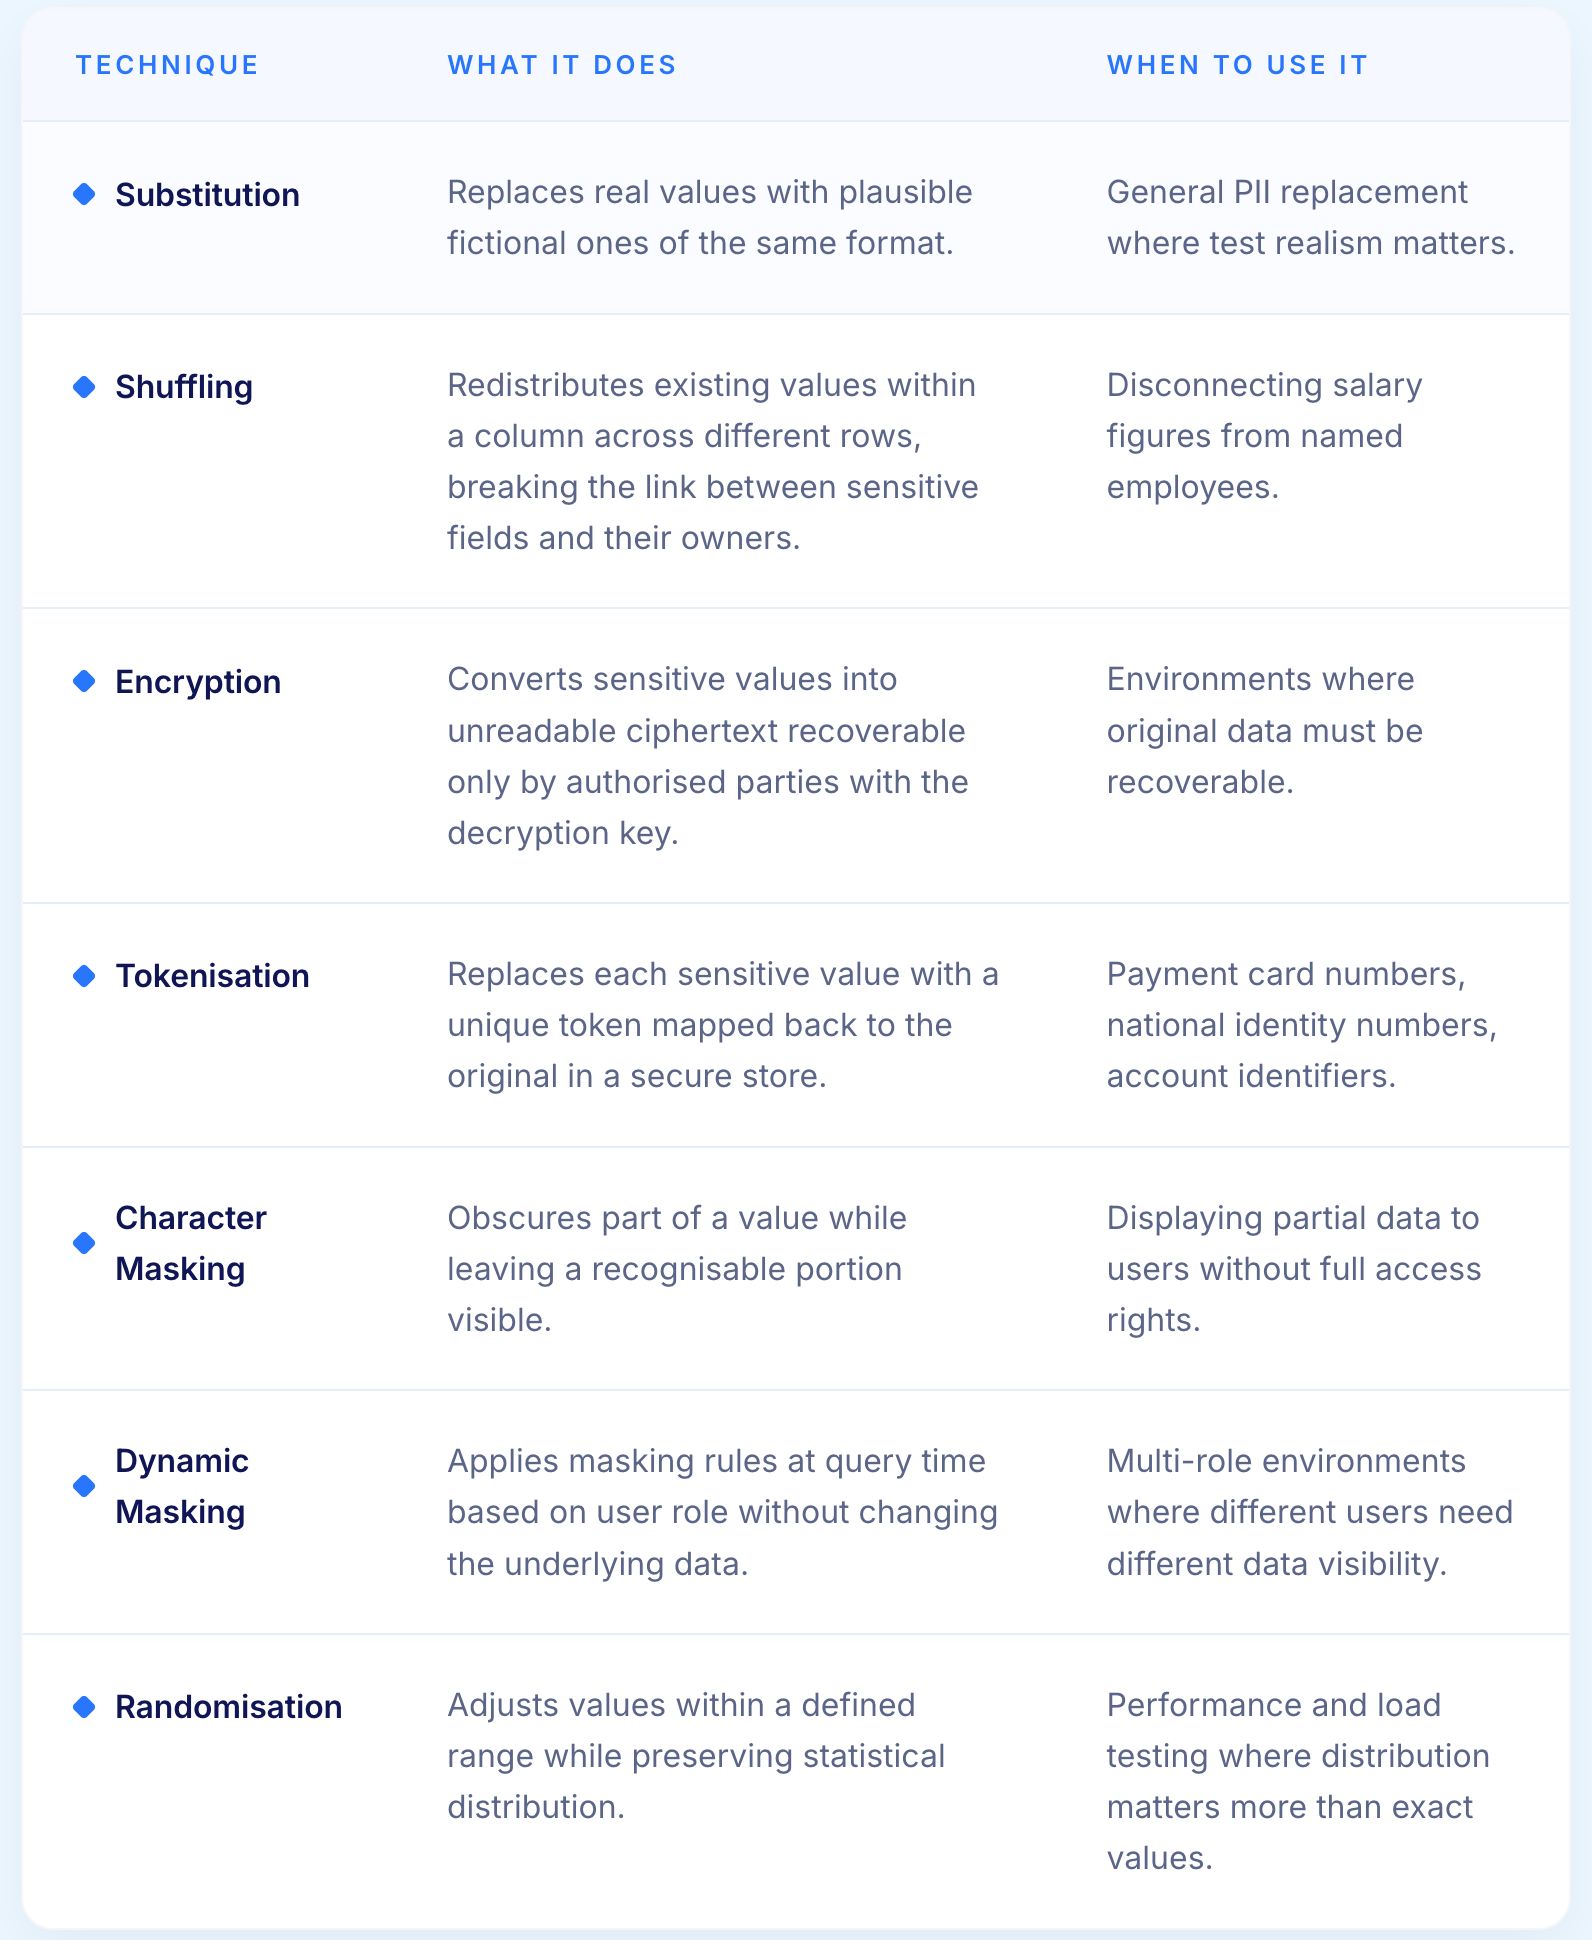
Data Masking: Replaces sensitive values with realistic but fictitious alternatives while preserving the format and structure the application expects
Data Anonymisation: Removes or generalises identifying information to a point where individuals cannot be re-identified from the dataset
Synthetic Replacement: Generates entirely artificial values for sensitive fields while retaining non-sensitive data intact
Access Controls: Restricts test environment access to authorised personnel with audit logging capturing who accessed what and when
Data Masking Techniques Compared
Masking is the most widely used protection method but the term covers several distinct approaches. Choosing the right technique depends on the sensitivity of the data, the compliance requirement, and how closely the masked version needs to resemble the original for testing purposes.
5. Maintain Data Currency
Outdated test data causes failures unrelated to actual application defects.
Problem
Tests reference product codes, customer accounts, or configuration values that no longer exist.
Solution
Establish data refresh strategies aligned with system changes:
Scheduled refreshes tied to release cycles
Event-driven updates when source data changes
Pre-execution validation checks
Automated alerts for stale data detection
Dynamic data generation avoids staleness by creating fresh data for each execution. AI-powered approaches eliminate static data maintenance entirely.
6. Document Data Requirements
Each test scenario should clearly define its data expectations.
Key Elements to Document
Required State: Data that must exist before execution
Created Data: Records generated during execution
Modified Data: Entities changed by the test
Cleanup Needs: Data that must be removed or reset
Clear documentation enables:
Verification of test independence
Automated data provisioning
Faster troubleshooting of data-related failures
Easier onboarding of new team members
7. Implement Data Cleanup
Without systematic cleanup, test data accumulates rapidly.
Problem
Thousands of test-created records pollute databases, degrading performance and increasing storage costs.
Solution
Adopt structured cleanup strategies:
Delete created records after test completion
Use transactional rollbacks where possible
Run scheduled cleanup jobs for test data
Periodically reset dedicated test environments
Tests should track the data they create. Naming conventions, metadata flags, or identifiers help reliably detect and remove test data in bulk.
8. Version and Roll Back Test Data
Testing is iterative, and reproducing defects often requires restoring prior data states.
Problem
During investigation, data is modified. Reproducing the original failure conditions requires time-consuming reprovisioning.
Solution
Implement data versioning capabilities:
Snapshot data states before test execution
Align data versions with release branches
Enable point-in-time rollback
Track data changes alongside code changes
Versioning allows teams to reproduce historical test conditions, compare outcomes across releases, and recover quickly from accidental data corruption.
Treat test data as a versioned artifact. AI-native test platforms reduce rollback dependency by generating fresh, reproducible data per execution while maintaining consistency through defined generation rules.

Test Data Management in DevOps and CI/CD
Modern software delivery relies on continuous integration and continuous deployment (CI/CD). Test data management must evolve accordingly, supporting automation, speed, parallelism, and repeatability across the delivery pipeline.
1. Shift-Left Testing Requirements
Shift-left methodologies move testing earlier in development. This approach requires test data availability from the earliest stages, not just during traditional QA phases. Developers need data when writing code, not after feature completion.
2. CI/CD Pipeline Integration
Automated pipelines trigger builds, tests, and deployments continuously. Test data provisioning must integrate seamlessly:
Automatic data provisioning on pipeline trigger
Data cleanup after test completion
Version-controlled data configurations
Environment-specific data variations
3. On-Demand Data Provisioning
Ephemeral environments spin up and tear down rapidly. Test data must provision programmatically through APIs and command-line interfaces. Manual data preparation cannot match infrastructure automation speed.
4. Parallel Execution Support
CI/CD pipelines run tests in parallel across multiple environments. Data isolation ensures parallel executions avoid conflicts. Each pipeline execution operates on independent data without interference.
5. Environment Consistency
Development, staging, and production environments require consistent data schemas and relationships while protecting production values. Configuration-driven provisioning ensures data compatibility across the pipeline.
Virtuoso QA integrates with CI/CD pipelines natively, providing API-driven test execution with AI-generated data that eliminates manual provisioning bottlenecks.
Test Data Management for Enterprise Applications
Enterprise applications present unique test data challenges.
1 Salesforce Test Data Considerations
Salesforce testing requires attention to:
Sandbox Data: Sandboxes may include production data copies or start empty. Plan data strategy accordingly.
Governor Limits: Salesforce imposes limits on data volumes, API calls, and storage. Test data strategies must respect limits.
Relationships: Complex object relationships (Account to Contact to Opportunity to Quote) require maintaining referential integrity.
Record Types and Profiles: Data validity depends on record types, profiles, and permission sets configured for test users.
Picklist Values: Picklist fields accept only predefined values. Test data must use valid selections.
AI powered data generation understands Salesforce context, producing records with valid picklist values, appropriate relationships, and compliant formats automatically.
2. Microsoft Dynamics 365 Test Data Considerations
Dynamics 365 testing requires attention to:
Entity Relationships: Complex entity relationships require coordinated data creation across related records.
Business Rules: Business rules validate data on save. Test data must satisfy rule requirements.
Security Roles: Data visibility depends on security roles assigned to test users.
Solutions and Customizations: Custom entities and fields require test data aligned with customization definitions.
Currency and Localization: Multi-currency and multi-language deployments need appropriate test data for each configuration.
3. Cross System Test Data
Enterprise journeys span multiple applications:
Example: Order to cash process touching CRM, ERP, and billing systems.
Cross system testing requires:
Coordinated Data: Matching identifiers across systems (customer IDs, order numbers)
Synchronized State: Consistent data state at journey start
Integration Awareness: Understanding how data flows between systems
Cleanup Coordination: Removing test data from all affected systems
Design data strategies addressing the complete journey, not just individual applications.
Building a Test Data Management Practice
Implementing effective Test Data Management requires more than tooling. It involves understanding current practices, defining clear data requirements, selecting appropriate strategies, and establishing governance to sustain improvements over time. The following steps provide a practical framework for introducing or maturing TDM capabilities.
1. Assess Current State
Before implementing TDM improvements, understand existing conditions:
How is test data currently created and maintained?
What data related test failures occur?
What sensitive data exists in test environments?
What compliance requirements apply?
What tools and processes currently exist?
Assessment reveals gaps and priorities for improvement.
2. Define Data Requirements
Document data needs systematically:
By Application Area: What data supports each feature or module
By Test Type: Different needs for smoke, regression, integration testing
By Environment: Development, staging, UAT requirements differ
By Compliance: Which data requires protection or anonymization
Requirements documentation guides strategy selection and implementation.
3. Select Appropriate Strategies
Match strategies to requirements:
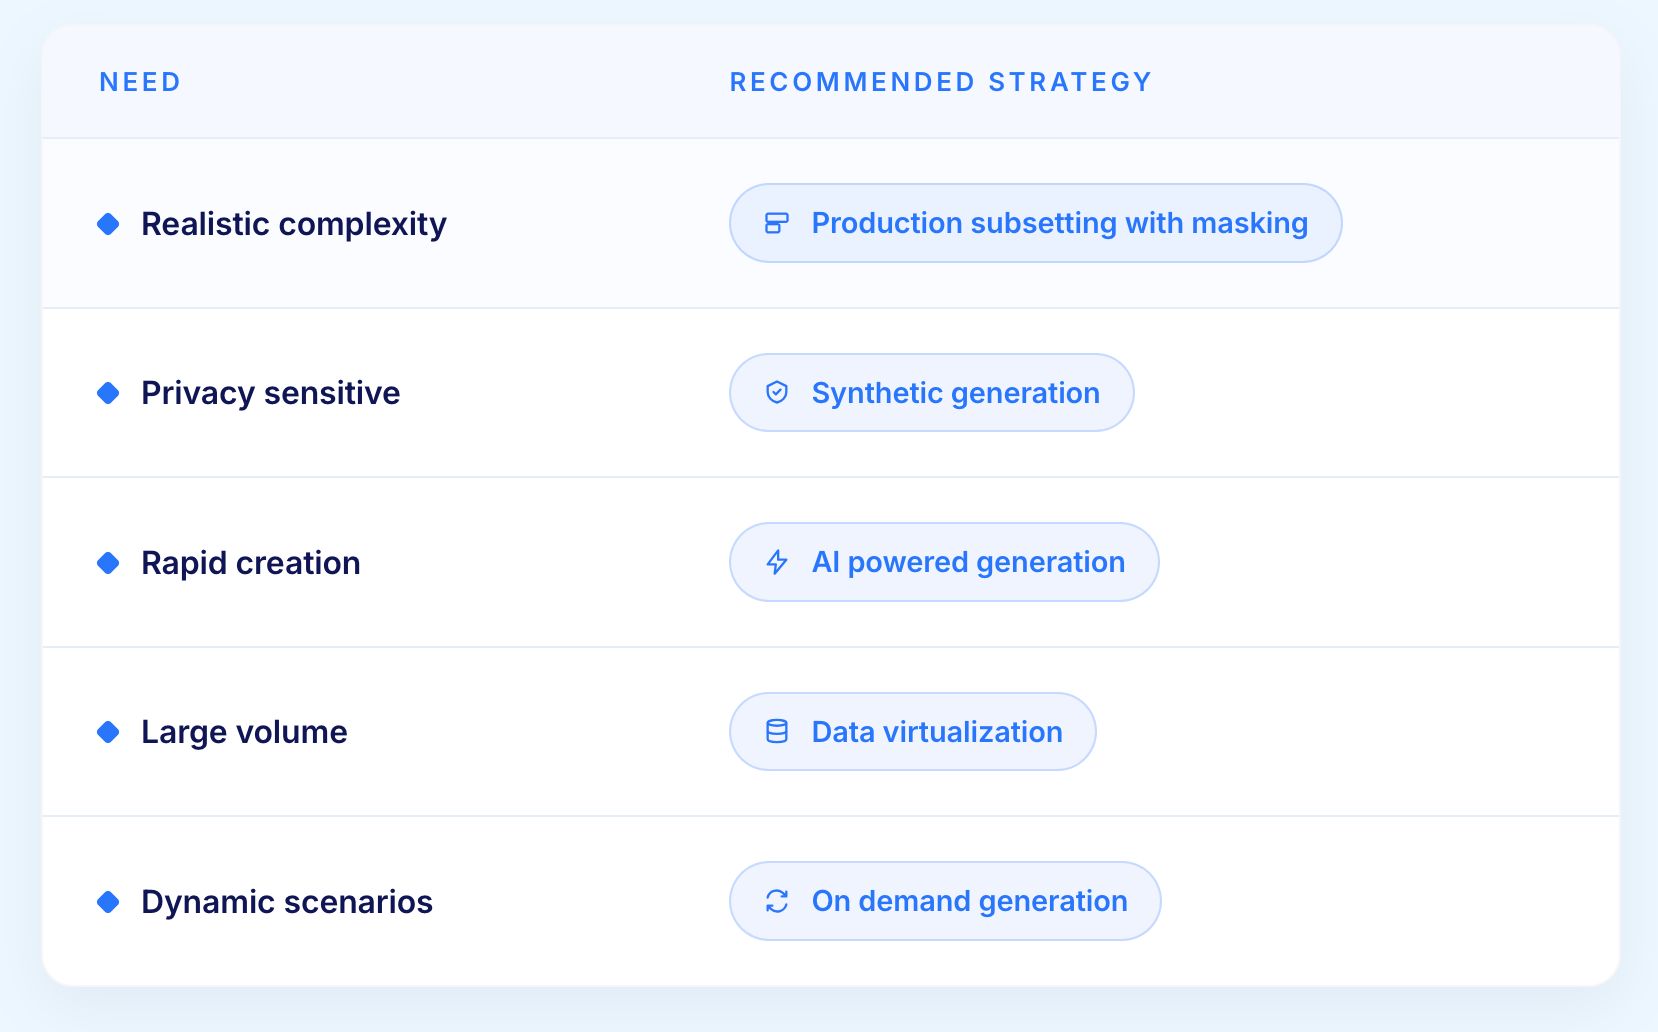
Most organizations implement multiple strategies for different needs.
4. Implement Tooling
Tools support TDM processes:
Data Masking Tools: Delphix, Informatica, IBM InfoSphere
Synthetic Generation: Broadcom Test Data Manager, GenRocket
AI Generation: Platform integrated capabilities like Virtuoso QA
Data Virtualization: Delphix, Actifio
Evaluate tools against requirements. Integrated platform capabilities reduce toolchain complexity.
5. Establish Governance
Sustainable TDM requires governance:
Ownership: Who is responsible for test data quality and availability
Policies: Rules for data creation, protection, and retention
Processes: How data requests are fulfilled and issues resolved
Metrics: How TDM effectiveness is measured and improved
Governance prevents regression to ad hoc practices.
Common Test Data Management Challenges
Organizations face recurring obstacles that undermine testing effectiveness and delay releases.
1. Slow, Manual Provisioning
Test environment setup often requires days or weeks. Teams queue requests behind others, waiting for DBAs and data engineers to extract, transform, and load data manually. Development velocity stalls while waiting for data.
2. Data Staleness and Drift
Test data becomes outdated as production systems evolve. Configuration changes, schema updates, and new product codes invalidate existing test data. Teams discover failures stem from data drift rather than application defects.
3. Sensitive Data Exposure
Production data contains PII, financial information, and protected health data. Using production data in test environments creates compliance violations and breach risks. Manual anonymisation is error-prone and time-consuming.
4. Referential Integrity Across Systems
Enterprise applications span multiple databases with complex relationships. Subsetting or masking data without preserving relationships produces invalid data that causes test failures unrelated to application functionality.
5. Insufficient Test Coverage
Limited or unrepresentative test data means edge cases go untested. Defects escape to production because test data failed to exercise the scenarios where problems occur.
6. Environment Conflicts and Data Collision
Multiple testers working simultaneously overwrite each other's data. Tests that passed individually fail when executed in parallel because shared data creates dependencies and race conditions.
7. Rising Storage and Infrastructure Costs
Full production copies for each test environment consume massive storage. Organisations maintain multiple redundant copies, multiplying infrastructure costs without improving test quality.
AI-native test data management addresses these challenges through intelligent generation, automated masking, and dynamic provisioning that eliminates manual bottlenecks.
Measuring Test Data Management Success
Key Metrics
Track metrics indicating TDM effectiveness:
Data Related Failure Rate: Percentage of test failures caused by data issues rather than application defects. Target: Below 5%.
Data Provisioning Time: Duration to prepare test data for execution. Trend toward automation and instant availability.
Data Freshness: Age of test data relative to source systems. Appropriate currency for test types.
Sensitive Data Exposure: Incidents of sensitive data in inappropriate environments. Target: Zero.
Data Maintenance Effort: Time spent maintaining test data. Trend toward reduction through automation.
Continuous Improvement
Use metrics to drive improvement:
Investigate data related failures for root causes
Automate manual data preparation activities
Expand generation capabilities to replace static data
Refine masking and anonymization approaches
Update governance based on incidents and near misses
TDM maturity develops over time through deliberate improvement.
Calculating Test Data Management ROI
Investments in Test Data Management (TDM) require clear business justification. ROI is typically measured across four key dimensions.
1. Provisioning Efficiency Gains
Automated, self-service data provisioning replaces manual extraction and DBA-dependent workflows.
Before TDM: Hours or days spent preparing data
After TDM: On-demand provisioning in minutes
ROI Calculation
(Weekly provisioning hours saved) × (Hourly labor cost) × 52
Typical Impact: 60–80% reduction in provisioning effort
2. Delivery Velocity Improvement
Faster data availability accelerates testing and release cycles.
Shorter test cycles
Faster environment setup
Elimination of data-related delays
ROI Calculation
(Days saved per release) × (Annual releases) × (Cost per delay day)
Typical Impact: 25–50% faster release cycles
3. Quality and Defect Reduction
Improved data quality increases defect detection and reduces production incidents.
Higher test coverage
Fewer false failures
Reduced escaped defects
ROI Calculation
(Reduced production defects) × (Average fix cost)
Typical Impact: ~30% reduction in production defects
4. Infrastructure Cost Optimization
Modern TDM minimizes data duplication and resource usage.
Data virtualization and subsetting
Lower storage and compute consumption
ROI Calculation
(Storage saved × cost per TB) + (Compute hours saved × hourly rate)
Typical Impact: 50–80% storage cost reduction
Building the Business Case
Total Annual Savings = Provisioning gains + Delivery velocity + Quality improvements + Infrastructure savings
Compare savings against licensing, implementation, training, and operating costs.
Typical ROI timeline: 6–12 months to positive return.
AI-native test platforms such as Virtuoso QA accelerate ROI by reducing tool sprawl and implementation effort through integrated test data capabilities.
Transform Test Data from Liability to Asset
Test data management determines whether automation delivers reliable value or constant frustration. The strategies and best practices presented here provide a roadmap from ad hoc data handling to systematic management.
AI native platforms transform TDM by generating contextually appropriate data on demand:
Natural language prompts describe data needs
Platform produces compliant, realistic values
Each execution receives fresh data
Static data maintenance disappears
Virtuoso QA's AI powered data generation eliminates the manual data burden that undermines automation initiatives. Combined with self healing tests and Live Authoring, organizations achieve testing transformation that traditional approaches cannot match.
Frequently Asked Questions on Test Data
Should we use production data for testing?
How do we handle test data for parallel test execution?
What is the difference between data masking and data anonymization?
How often should test data be refreshed?
How do we manage test data for enterprise applications like Salesforce?